Building High-Performance AI Decision Services with Jev
Admin
September 20, 2026
Why System One Models Matter for Modern Backends
In today’s hyper‑scalable world, developers need AI that can make split‑second, reliable decisions without the baggage of free‑form text generation. Traditional LLMs excel at conversation but introduce latency, hallucination risk, and costly token consumption. System One Models, exemplified by TypeSafe AI’s Jev, flip the script: they are purpose‑built for structured, high‑confidence decisions that can be directly consumed by software.
By integrating a System One Model into your microservices, you gain sub‑100 ms response times, deterministic output shapes, and built‑in confidence scores. This translates to faster request routing, smarter automation, and more robust guardrails—all essential for production‑grade AI‑driven workflows.
Core Architecture of Jev and Its Advantages
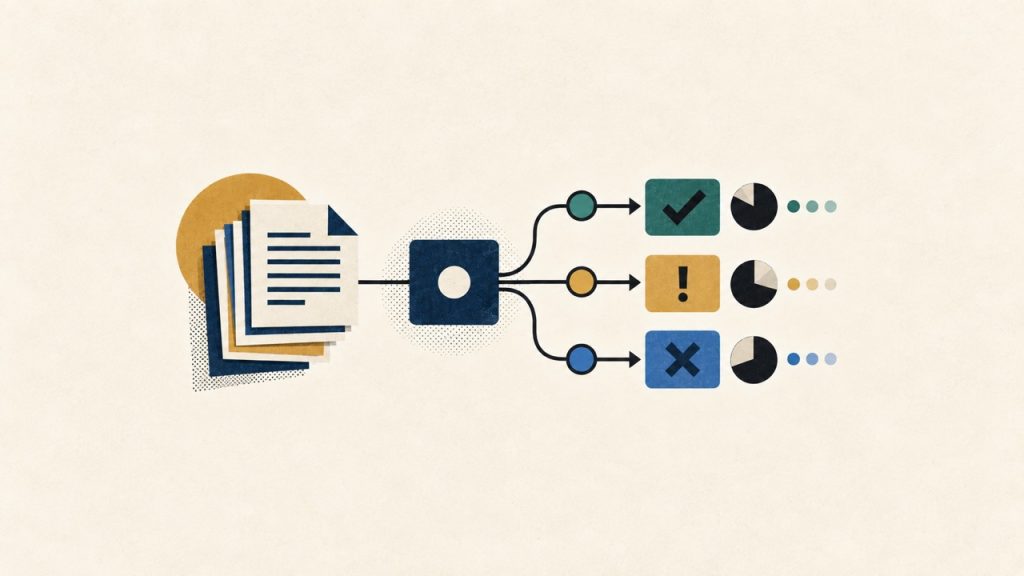
Jev represents a new class of frontier models that prioritize speed, type safety, and calibrated uncertainty. Instead of autoregressively generating tokens, it emits parallel, typed decisions with probability distributions attached to each possible outcome. This design eliminates type errors and hallucinations, making it ideal for backend automation.
Parallel Sampling: All outputs are generated in a single query, slashing latency.
Calibrated Probabilities: Every decision includes honest confidence scores.
Zero‑Cost Structured Outputs: Output tokens are practically free, unlike the expensive strings from LLMs.
RLCD Training: Reinforcement Learning for Calibrated Decisions ensures the model knows when it’s uncertain.
Parallel Sampling & Calibrated Probabilities
Because Jev returns a batch of possibilities at once, you can evaluate the most probable branch without waiting for token‑by‑token generation. The accompanying confidence scores let you decide whether to trust the result or fall back to a safe default.
/**
 * Example: Call Jev for a routing decision.
 * Assumes a REST endpoint that expects JSON input and returns typed probabilities.
 */
const axios = require('axios');

async function routeRequest(payload) {
  const response = await axios.post('https://api.typesafe.ai/v1/decide', {
    model: 'jev',
    input: payload.state,
    schema: payload.schema // JSON‑Schema defining possible outputs
  }, { timeout: 200 }); // 200 ms timeout for sub‑100 ms SLA

  const { decision, confidence } = response.data;

  if (confidence < 0.7) {
    // Low confidence – fall back to a deterministic rule
    return { decision: 'fallback', confidence };
  }

  return { decision, confidence };
}

// Usage
const result = await routeRequest({
  state: { userId: 123, amount: 5000 },
  schema: {
    type: 'object',
    properties: {
      decision: { type: 'string', enum: ['approve', 'decline', 'review'] },
      confidence: { type: 'number' }
    }
  }
});
console.log(result);
Integrating Jev into a Microservice
Below is a pragmatic, step‑by‑step pattern for embedding Jev into a Node.js/Express microservice while keeping the codebase clean and testable.
Define a Contract: Create a JSON‑Schema that describes every possible structured output. This becomes the API’s OpenAPI spec and guarantees type safety.
Wrap the External Call: Use an async helper that abstracts the Jev endpoint, adds retries, circuit‑breaker logic, and a hard timeout (e.g., 200 ms).
Implement Business Logic: Consume the decision and confidence, applying domain rules (e.g., approve only if confidence ≥ 0.8).
Cache & Observability: Store recent decisions in a fast cache (Redis) to reduce repeated calls, and emit metrics (latency, confidence distribution) to your monitoring stack.
Guardrails: Add a fallback service that reverts to a safe default when Jev is unavailable or confidence is too low.
/**
 * microservice.js – Express route that uses Jev for a risk assessment.
 */
const express = require('express');
const { JevClient } = require('./jevClient');
const redis = require('redis');
const client = redis.createClient({ url: process.env.REDIS_URL });
const app = express();
app.use(express.json());

// Initialize Jev client with timeout & circuit breaker
const jev = new JevClient({
  endpoint: process.env.JEV_API_URL,
  timeout: 200,
  maxRetries: 2,
  circuitBreakerThreshold: 5
});

// Risk assessment schema (JSON‑Schema)
const riskSchema = {
  type: 'object',
  properties: {
    riskLevel: { type: 'string', enum: ['low', 'medium', 'high'] },
    confidence: { type: 'number', minimum: 0, maximum: 1 }
  },
  required: ['riskLevel', 'confidence']
};

app.post('/assess', async (req, res) => {
  const cacheKey = `assess:${Buffer.from(JSON.stringify(req.body)).toString('base64')}`;

  // 1. Try cache first
  const cached = await client.get(cacheKey);
  if (cached) {
    return res.json(JSON.parse(cached));
  }

  // 2. Call Jev
  try {
    const { decision, confidence } = await jev.decide({
      input: req.body,
      schema: riskSchema
    });

    const result = { decision, confidence };

    // 3. Store in cache (5 min TTL)
    await client.setex(cacheKey, 300, JSON.stringify(result));

    // 4. Emit metrics (pseudo‑code)
    metrics.observe('jev.latency', Date.now() - req.startTime);
    metrics.gauge('jev.confidence', confidence);

    res.json(result);
  } catch (err) {
    // Fallback – safe default
    const fallback = { decision: 'unknown', confidence: 0 };
    res.status(503).json(fallback);
  }
});

app.listen(3000, () => console.log('Risk assessment microservice listening on 3000'));
Production‑Ready Patterns & Guardrails
Always treat external AI services as a dependency: define clear SLAs, implement circuit breakers, and have a deterministic fallback that preserves system stability.
When you embed Jev, think of it as a “smart if‑statement” rather than a black box. Keep the surrounding code simple, validate every input against the schema, and log both the decision and confidence for auditability.
Additionally, consider using feature flags to roll out Jev gradually. You can start with low‑traffic endpoints, monitor confidence distributions, and adjust thresholds before scaling to mission‑critical paths.
Key Takeaways
System One Models like Jev give backend engineers a new tool for ultra‑low‑latency, type‑safe AI decisions. By embracing parallel sampling, calibrated probabilities, and structured outputs, you can build microservices that are both fast and reliable.
Design your API contracts first – JSON‑Schema drives type safety.
Wrap Jev calls with timeouts, retries, and circuit breakers to protect your services.
Cache frequent decisions and expose confidence metrics for observability.
Always have a deterministic fallback to keep the system resilient.
Iterate incrementally with feature flags to safely adopt System One Models in production.
Integrating Jev isn’t just an engineering upgrade; it’s a strategic shift toward automation‑first architectures that can scale with confidence. Start small, measure often, and let the calibrated decisions drive your next‑gen AI‑enabled services.
Discussion (0)
Share your thoughts with the community